1X Redwood AI
$ 0
Vision-language transformer for end-to-end manipulation in human environments on NEO robots
Showing 1–16 of 96 results
Vision-language transformer for end-to-end manipulation in human environments on NEO robots
Physics-based world model using video/prompts; enables NEO robots to learn by observation
ACT-2 is Sunday Robotics’ second robot model, built to make its Memo home robot reliable in real homes. In tests, it folded laundry successfully 99% of the time.
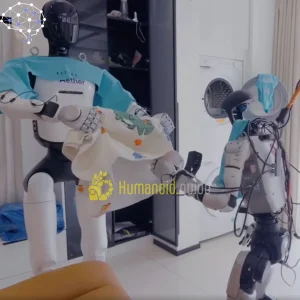
Aether Space is a brain-inspired foundation model for humanoid robots. JoyIn, a Suzhou-based company, built it to give robots memory, physical intuition and fast body control.
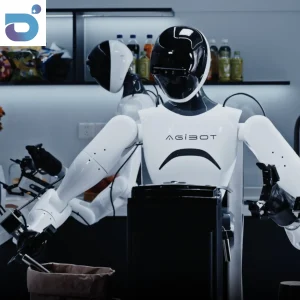

Vision-language AI using ViLLA framework for scene understanding, action planning and execution
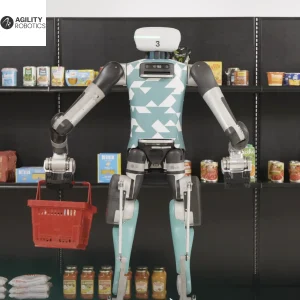

“Motor cortex” foundation model for Digit humanoid ensuring stability across varied tasks
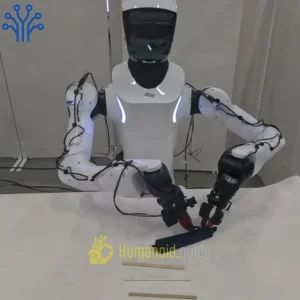
AIRoA-0 is an open robot foundation model from Japan’s AI Robot Association. It learned two-arm skills from human recordings instead of robot data, and it runs on many different robots.
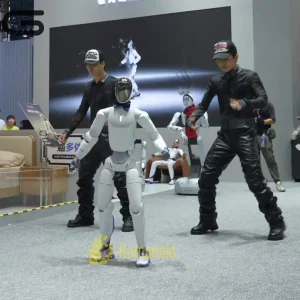
AstraBrain is Galbot’s embodied AI system. It combines a planning brain with a whole-body controller, so the company’s robots can predict outcomes, move naturally and handle real-world tasks.
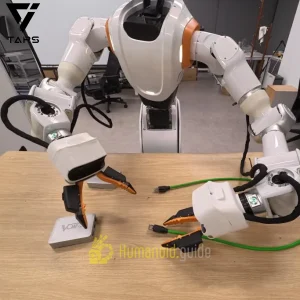
AWE 3.0 is TARS’s embodied AI model for precise industrial work. It combines sight and touch, so its dexterous robot hand can handle delicate tasks and correct mistakes on its own.

Hand motion generation model for dexterous manipulation; pretrained on massive human manipulation videos; enables robotic hands to master new tasks with minimal real robot data
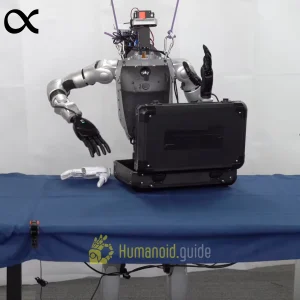
Being-H0.5 is BeingBeyond’s open robot model that learns from human hand activity to control many kinds of robots, from humanoids to dexterous arms.
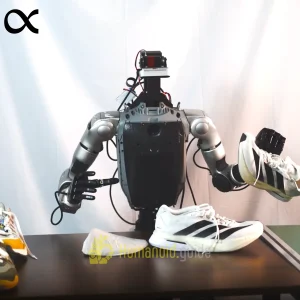
Being-H0.7 is BeingBeyond’s world-action model that learns from huge amounts of human video. It plans ahead in a hidden space and drives dexterous robot hands in real time.
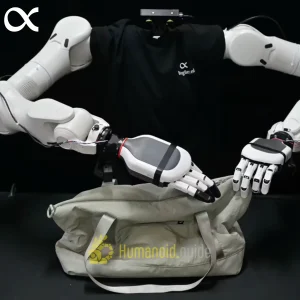
Being-H0.8 is BeingBeyond’s touch-aware robot foundation model. It learns from human video labeled with touch to help robot hands handle delicate, contact-heavy tasks.
Whole-body motion generation model learning general human behavioral patterns from large-scale video; bridges robot brain and body; generates full-body motion sequences from high-level task instructions
Next-gen multimodal foundation model for robotics; unifies 3D spatial understanding, language intent, perception, cognition, reasoning and planning for autonomous navigation and task execution
Low-level whole-body control model for humanoid robots; trained with RL on massive human data; achieves stable zero-shot execution of full-body motion commands


