Reward AI unveils OM-1 model trained on human demonstrations
Reward AI has emerged from stealth with OM-1, a robot foundation model it says is trained entirely from human demonstrations rather than robot teleoperation. In a LinkedIn post, 22Astronauts founder Ilir Aliu described the launch and its Omnibody Hand, a hand worn device that records motion, tactile information, proximity, vision and position while a person performs a task.
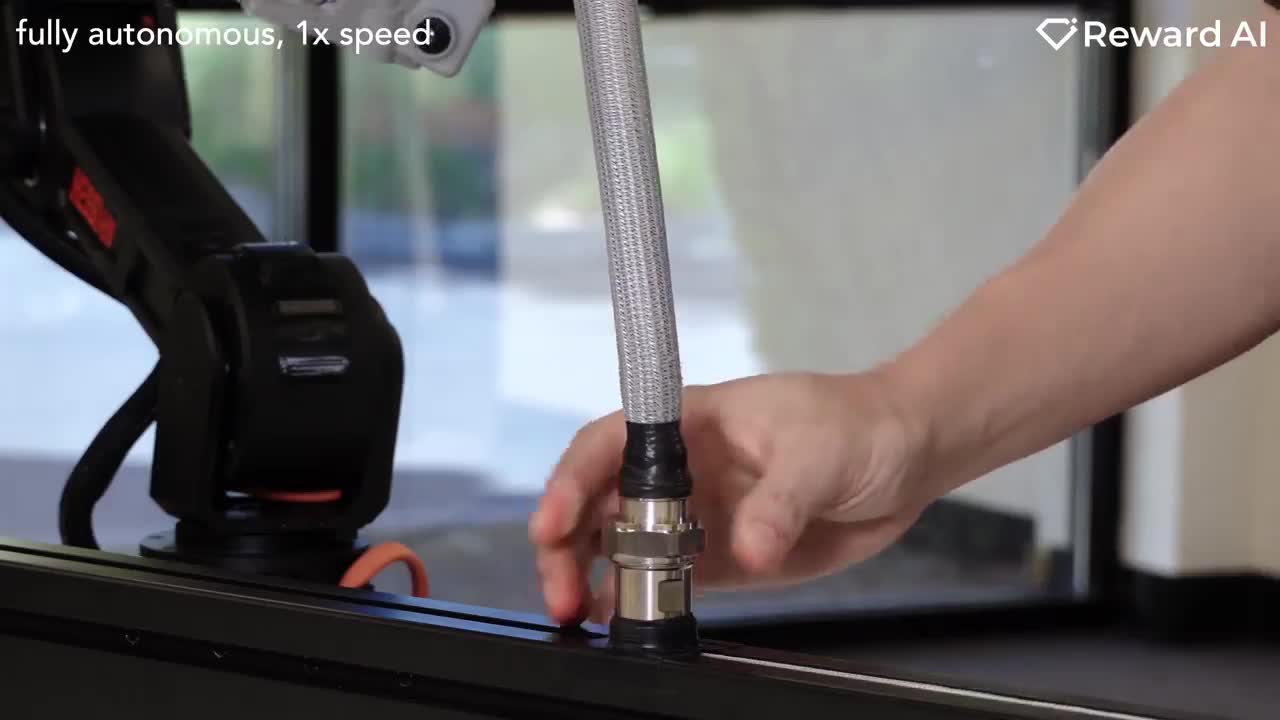
According to Aliu, the captured data can train OM-1 to control different robot bodies. Reward describes the concept as “One Model, One Data Interface, Any Body.” The company claims a new task can be learned from less than 30 minutes of human demonstration data without collecting additional robot data. Aliu said launch videos show four robot arms packaging a phone, robots folding laundry and mixing cocktails, an arm unplugging an Ethernet cable, and early humanoid experiments. Some longer tasks reportedly finish in real time in under 30 seconds.
Aliu linked Reward’s approach to DexCap, Stanford work from 2024 on capturing human dexterous manipulation and transferring it to robots. Chen Wang, C. Karen Liu and Li Fei-Fei were among the researchers involved, he wrote. A data layer that transfers between embodiments could reduce repeated teleoperation as robot hardware changes, but the evidence remains preliminary. Reward has released no paper or open model, and it has not published large scale success rate data needed to assess robustness.
Source: Ilir Aliu on LinkedIn